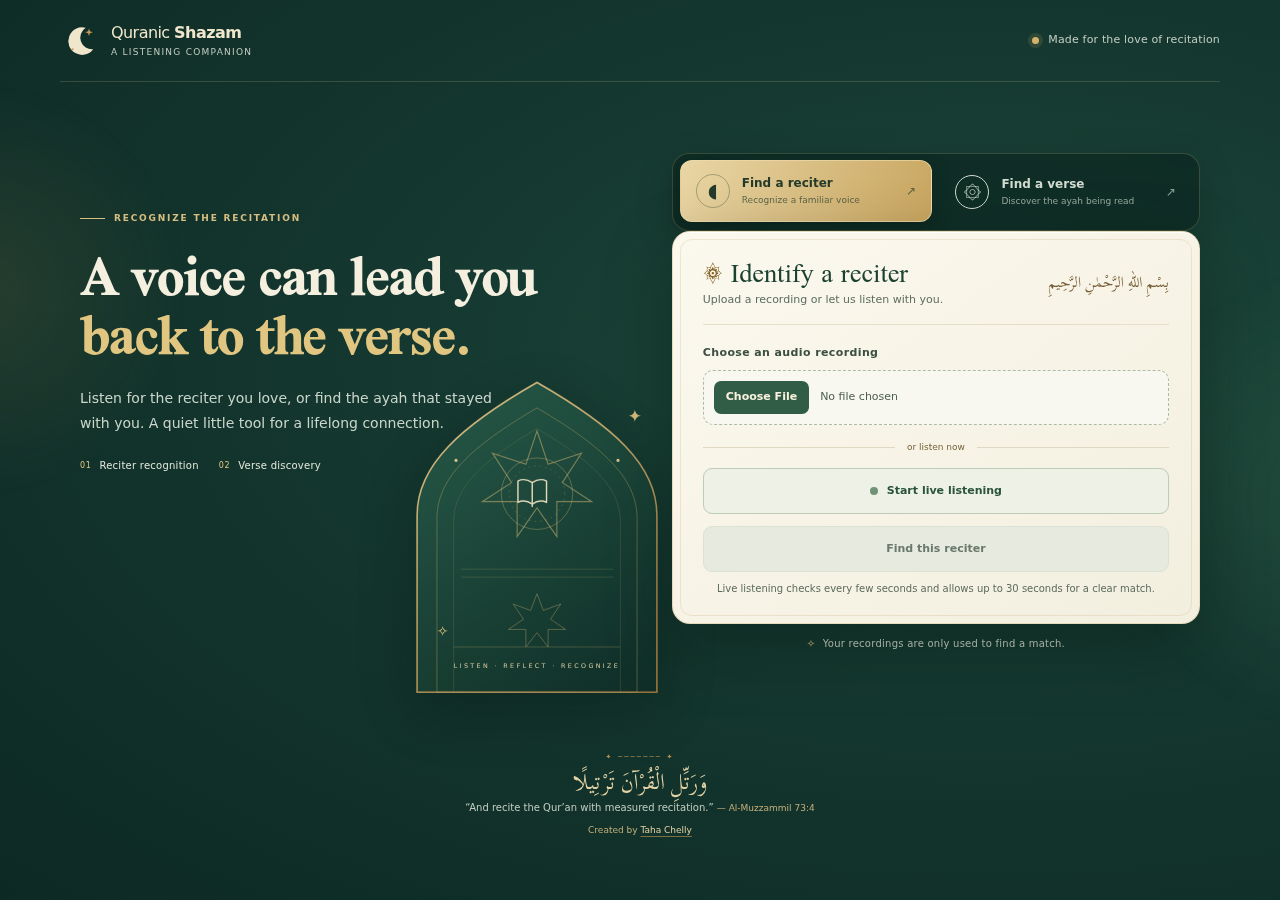
 Taha ChellyQuranic Shazam
When an audio match needs more context
Separating speaker recognition from verse discovery, and making uncertainty part of the listening flow.
Taha Chelly
Technical decisions, explained.
Taha ChellyQuranic ShazamSeparating speaker recognition from verse discovery, and making uncertainty part of the listening flow.
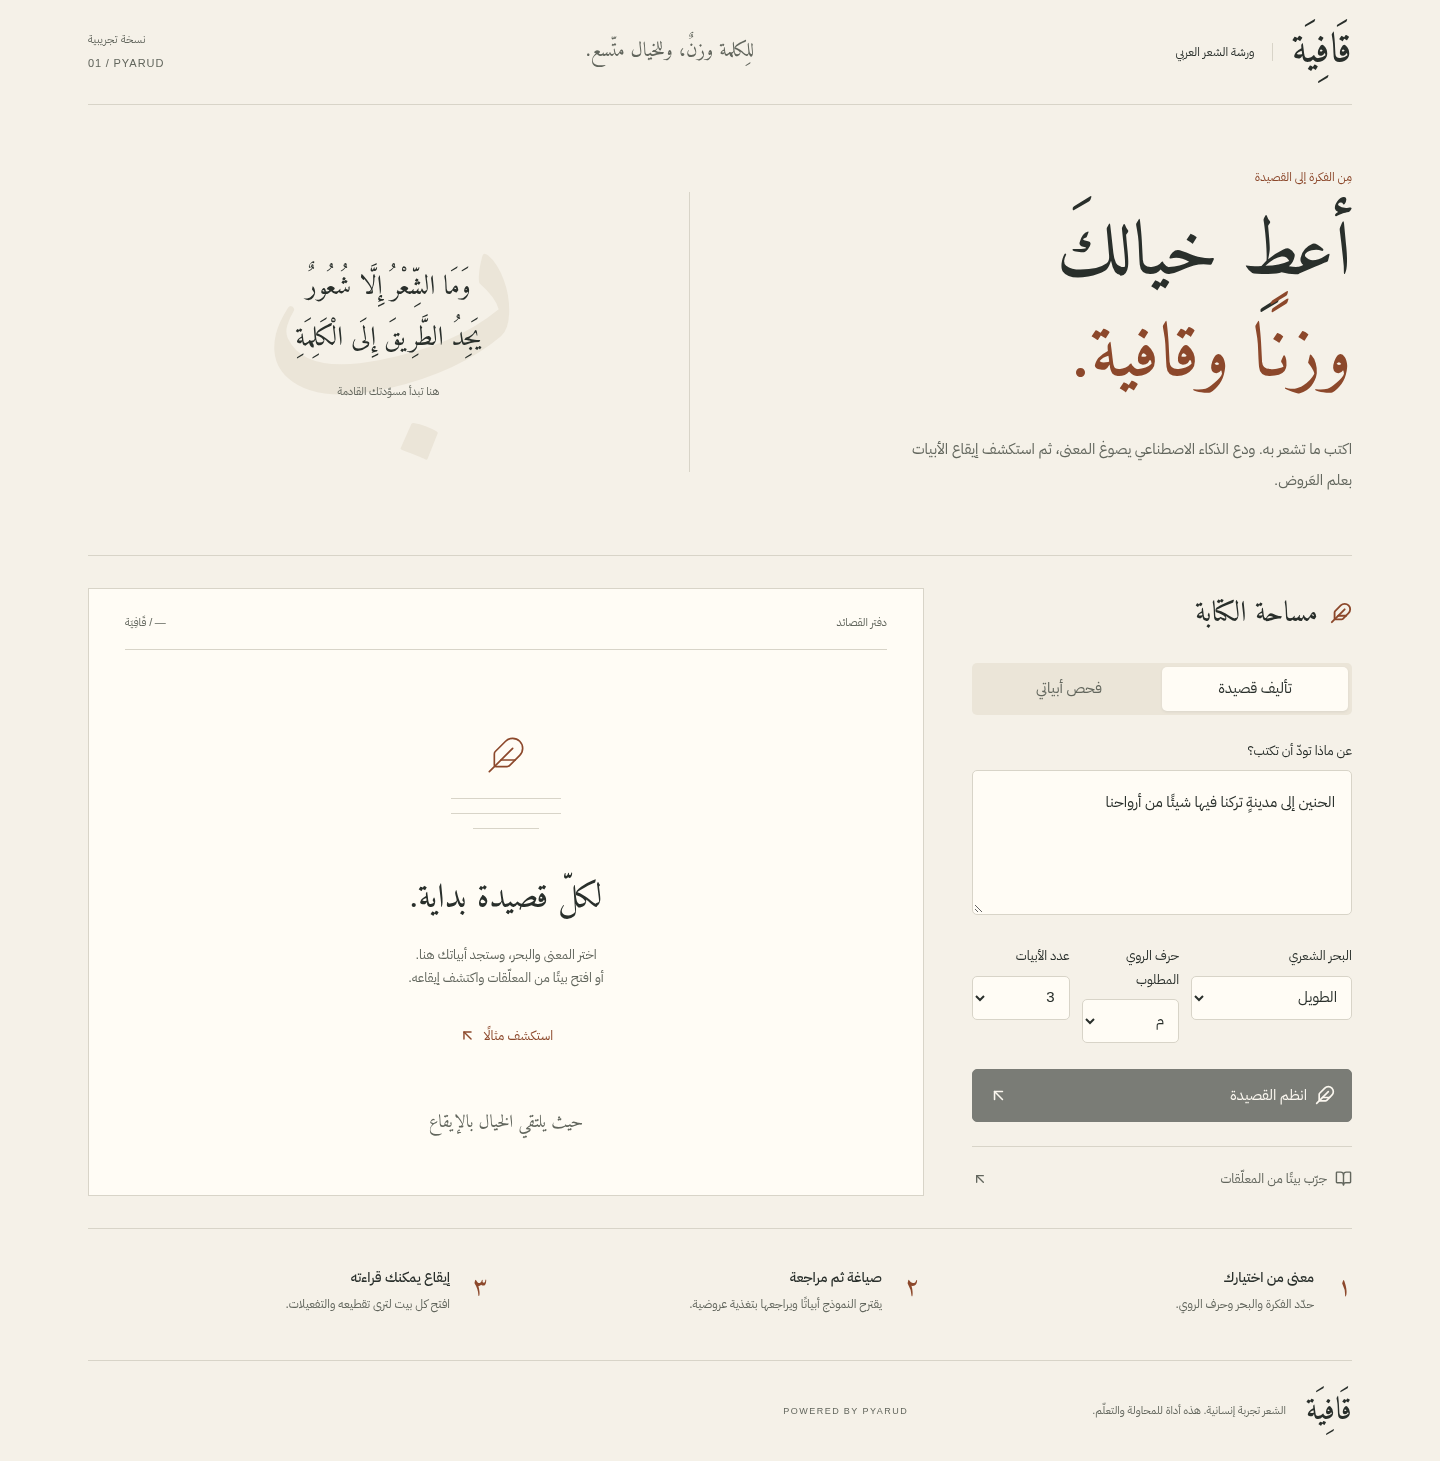
Taha ChellyQafiyaA 4.8 MB vocalization model, preserved vowel marks, and explicit limits on what automated analysis can claim.