Recognize the reciter
An ECAPA-TDNN model creates a voice embedding. ONNX Runtime runs inference, then cosine similarity ranks matches against profiles for 20 reciters.
AUDIO · AI · WEB
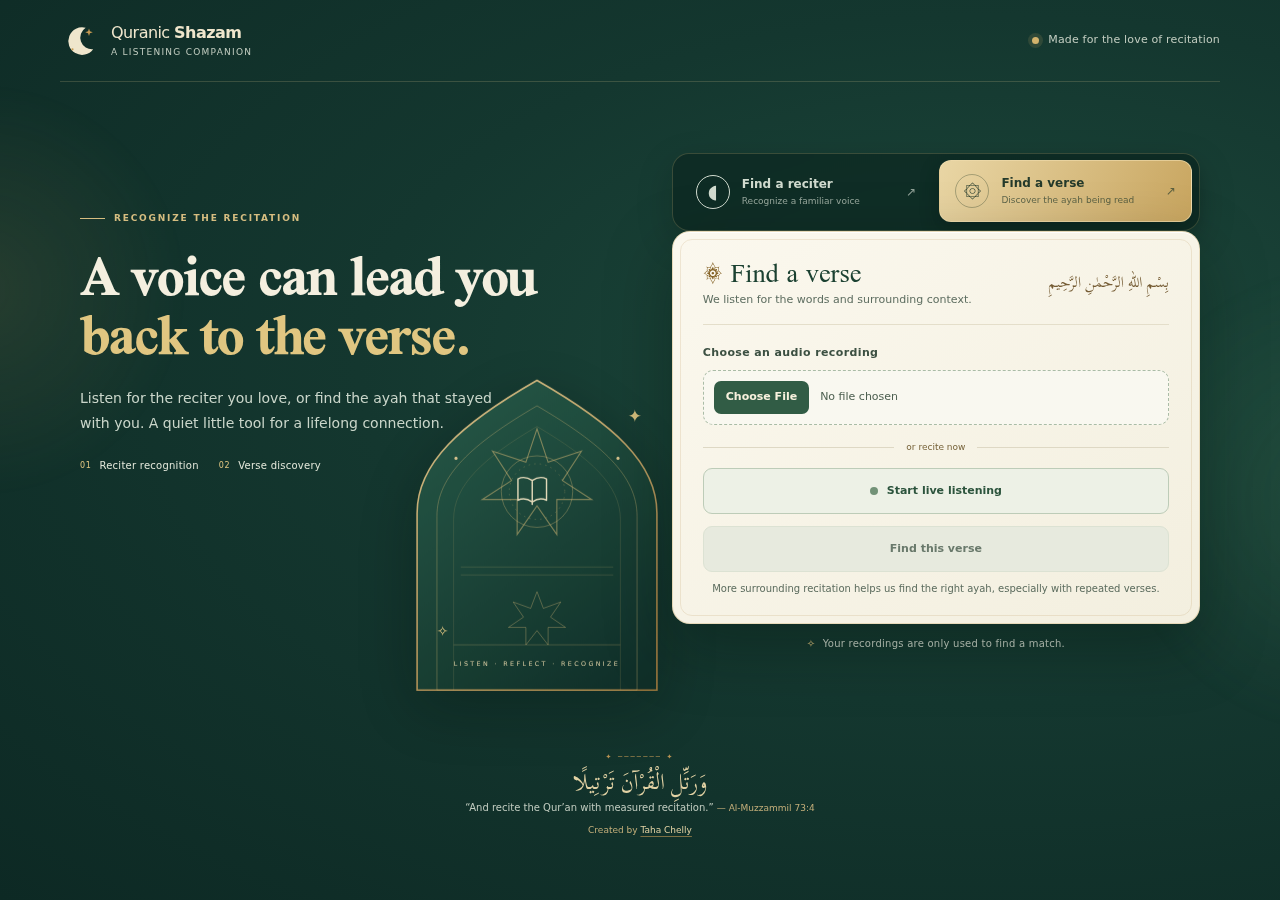
Discover who is reciting and which verse you’re hearing. An audio recognition app for Qur’an recitation, with live listening and file uploads.
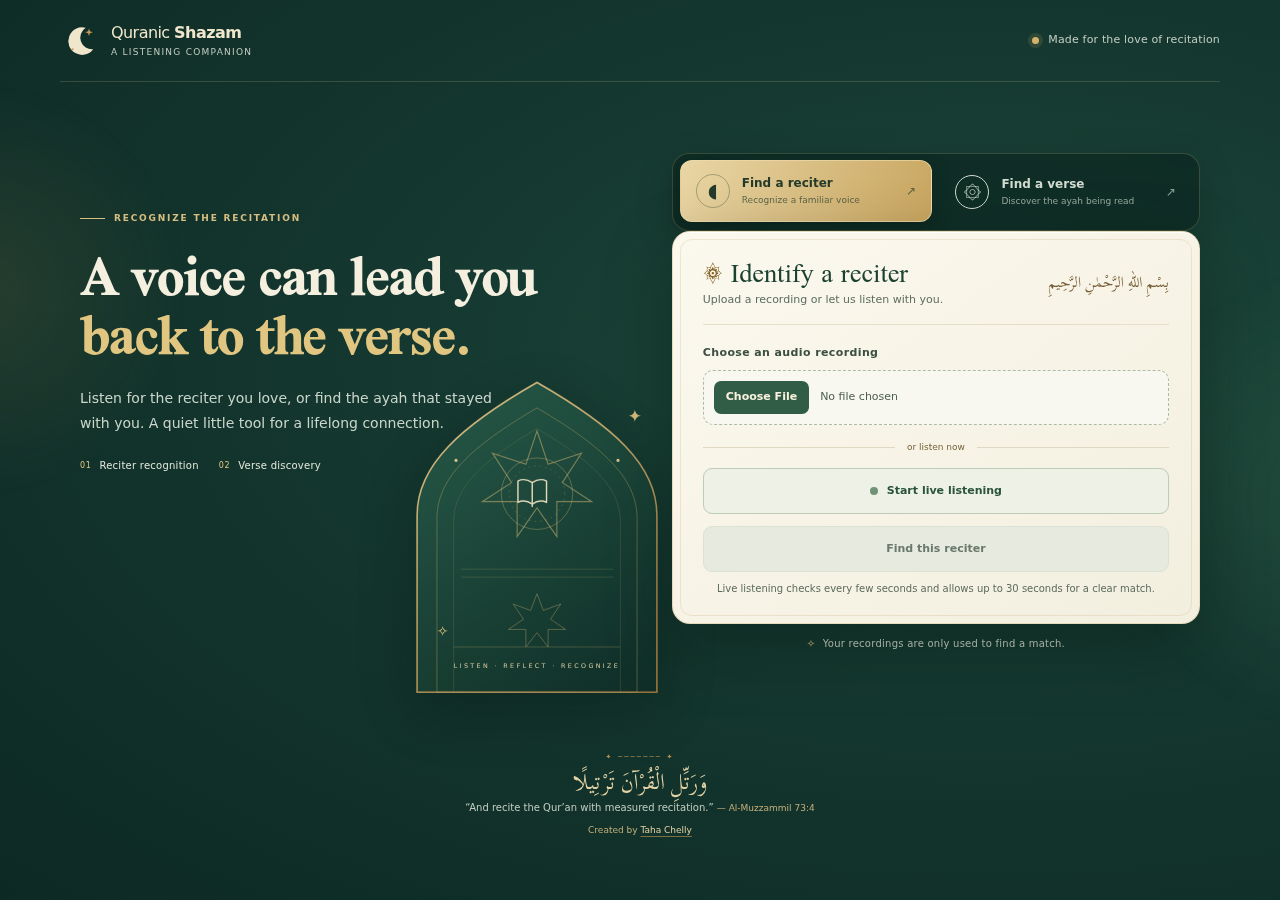
An ECAPA-TDNN model creates a voice embedding. ONNX Runtime runs inference, then cosine similarity ranks matches against profiles for 20 reciters.
A Quran-tuned Whisper model transcribes the Arabic audio. Normalized text is matched against 6,236 verses to find likely surah and ayah matches.
When a verse match is ambiguous, progressive listening gathers more audio context. Uncertain results stay marked as uncertain.
Frontend: React 19 and TypeScript, built with Vite and Tailwind CSS 4. Browser microphone capture and file uploads connect to the API.
Backend: Python and FastAPI, with WebSockets for live reciter recognition. ONNX Runtime handles speaker embeddings; faster-whisper and CTranslate2 handle verse transcription.
Delivery: Docker containers on Render, with Nginx serving the frontend. GitHub Actions checks the backend and frontend before deploying affected services.


